Claude Fable 5.2 at a glance
Anthropic released Claude Fable 5.2 and Mythos 5.2 on November 9, 2026. As of November 9, 2026, Fable 5.2 ranks #1 on the Artificial Analysis Intelligence Index (64.6 at max effort). It costs $8 per million input tokens and $40 output, with a fast mode at $16/$80.
Current standing
As of
- Rank
- #1of 45 models
Claude Fable 5.2 (Max) · 64.6 on the Artificial Analysis Intelligence Index v5.0.1 (opens in a new tab)
- Recorded at publication
- 64.6 (v5.0.1)
as of
- Current leader
- Still the top model in this snapshot.
Computed from our daily snapshot; it changes as new models are measured. Claude Fable 5.2 and Mythos 5.2: Anthropic's new flagship tops the AI Intelligence Index at $8 per million input tokens
What changed with Claude Fable 5.2
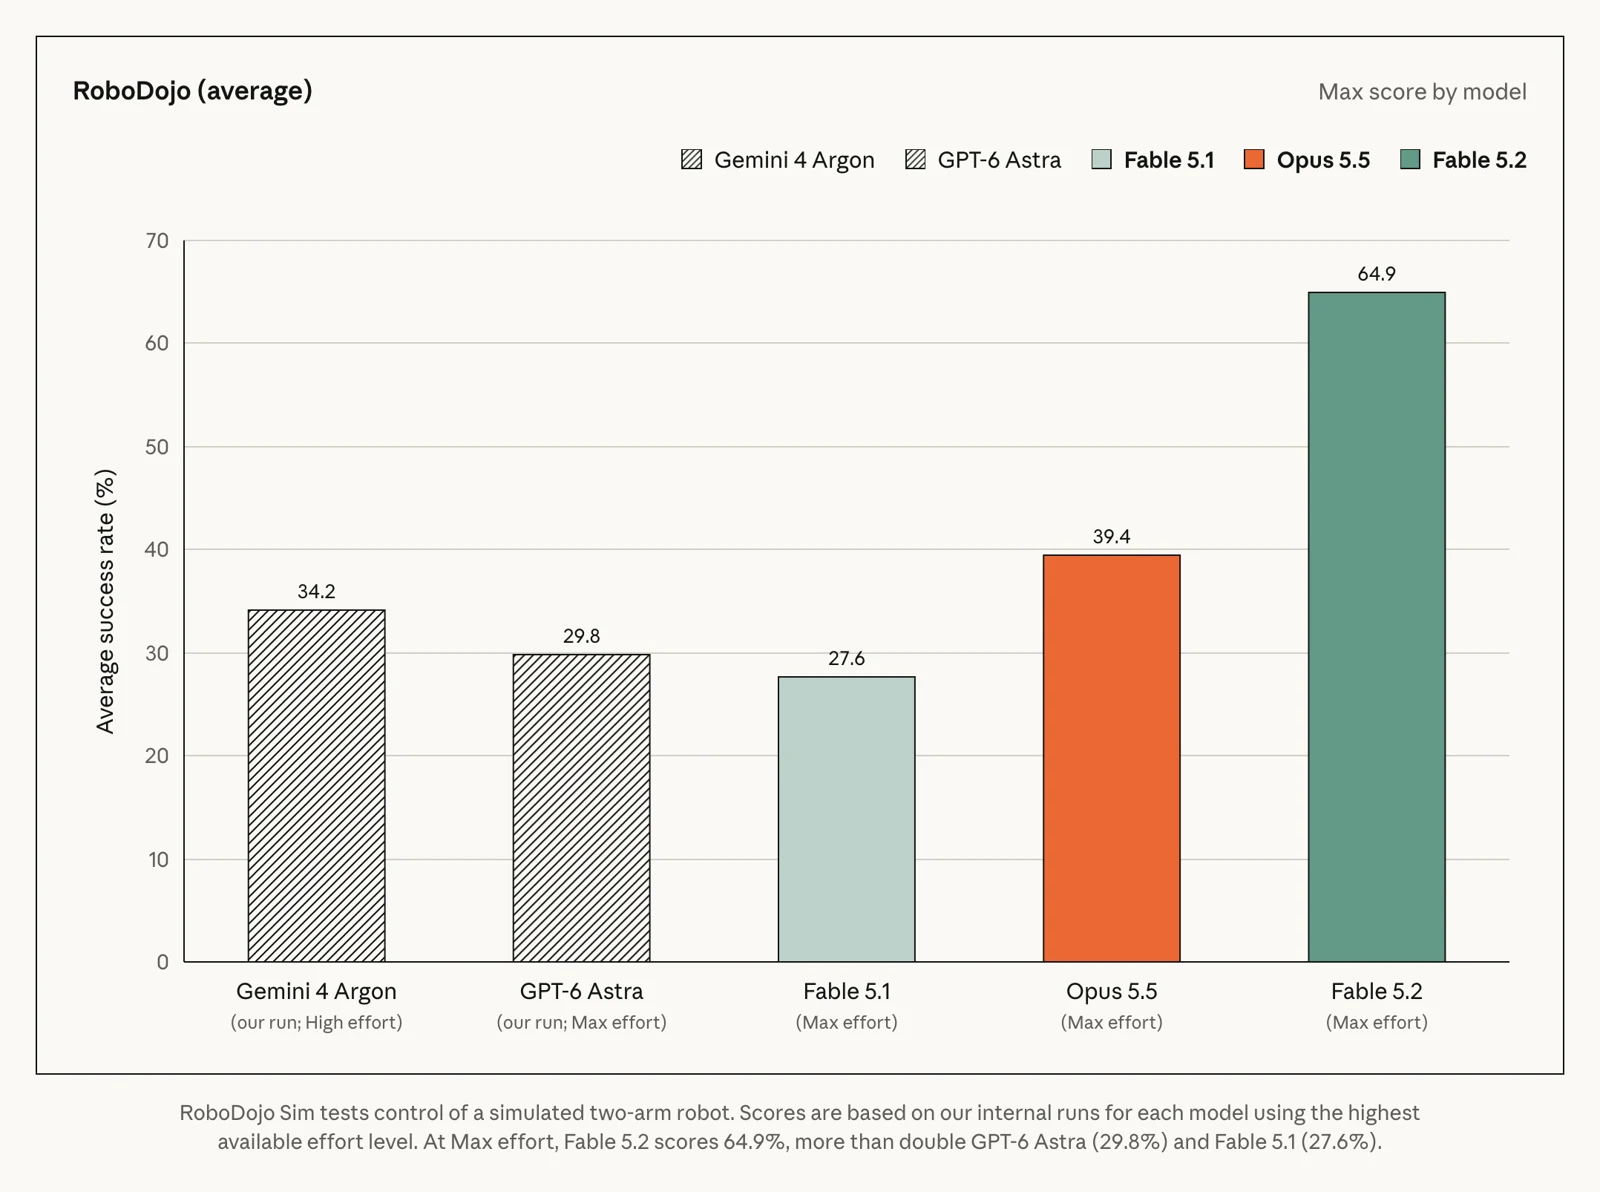
Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 on November 9, 2026, upgrading the models it builds for the most daunting technical challenges. The two are the same underlying model: Fable 5.2 is the public version, with strong cybersecurity and biology safeguards, while Mythos 5.2 drops some of those safeguards for vetted organizations in Anthropic's Cyber and Life Sciences Verification Programs. Fable 5.2 is available today on the Claude Platform as claude-fable-5-2, on Amazon Web Services, Google Cloud and Microsoft Azure, and in Claude subscriptions. Anthropic says the new models communicate more clearly than Fable 5.1 and generate outputs up to 30% faster.
On the Artificial Analysis Intelligence Index, Claude Fable 5.2 at max effort scores 64.6, which as of November 9, 2026 ranks it #1 of the 59 model families Artificial Analysis scores, ahead of Google's Gemini 4 Carbon at 60.0 and Claude Opus 5.5 at 59.1. Its lower effort settings stay near the top: 62.2 at xhigh, 61.8 at high, 56.4 at medium and 53.9 at low. In Anthropic's own benchmark table, Fable 5.2 leads Opus 5.5 on FrontierCode 2.0 agentic coding (49.1% at xhigh against 45.5%), Humanity's Last Exam with tools (74.2% against 67.7%) and OSWorld 2.1 computer use (89.3% against 87.2%). It does not win everything: Gemini 4 Carbon beats it on AutomationBench business workflows (53.9% against 51.4%).
Fable 5.2 costs $8 per million input tokens and $40 per million output tokens, down from Fable 5.1's $10 and $50, and an optional fast mode speeds up token generation by up to 2.5 times at $16 and $80. Running the full Artificial Analysis index costs $22,191 at max effort, $7,106 at high and $3,360 at medium, so the effort setting is the main cost control: Anthropic's docs set high as the API default, medium is the default in Claude apps and Claude Code, and adaptive thinking is always on. In Anthropic's testing, Fable 5.2 at high effort scored about level with Opus 5.5 at max effort on FrontierCode 2.0, for roughly half the cost per task.
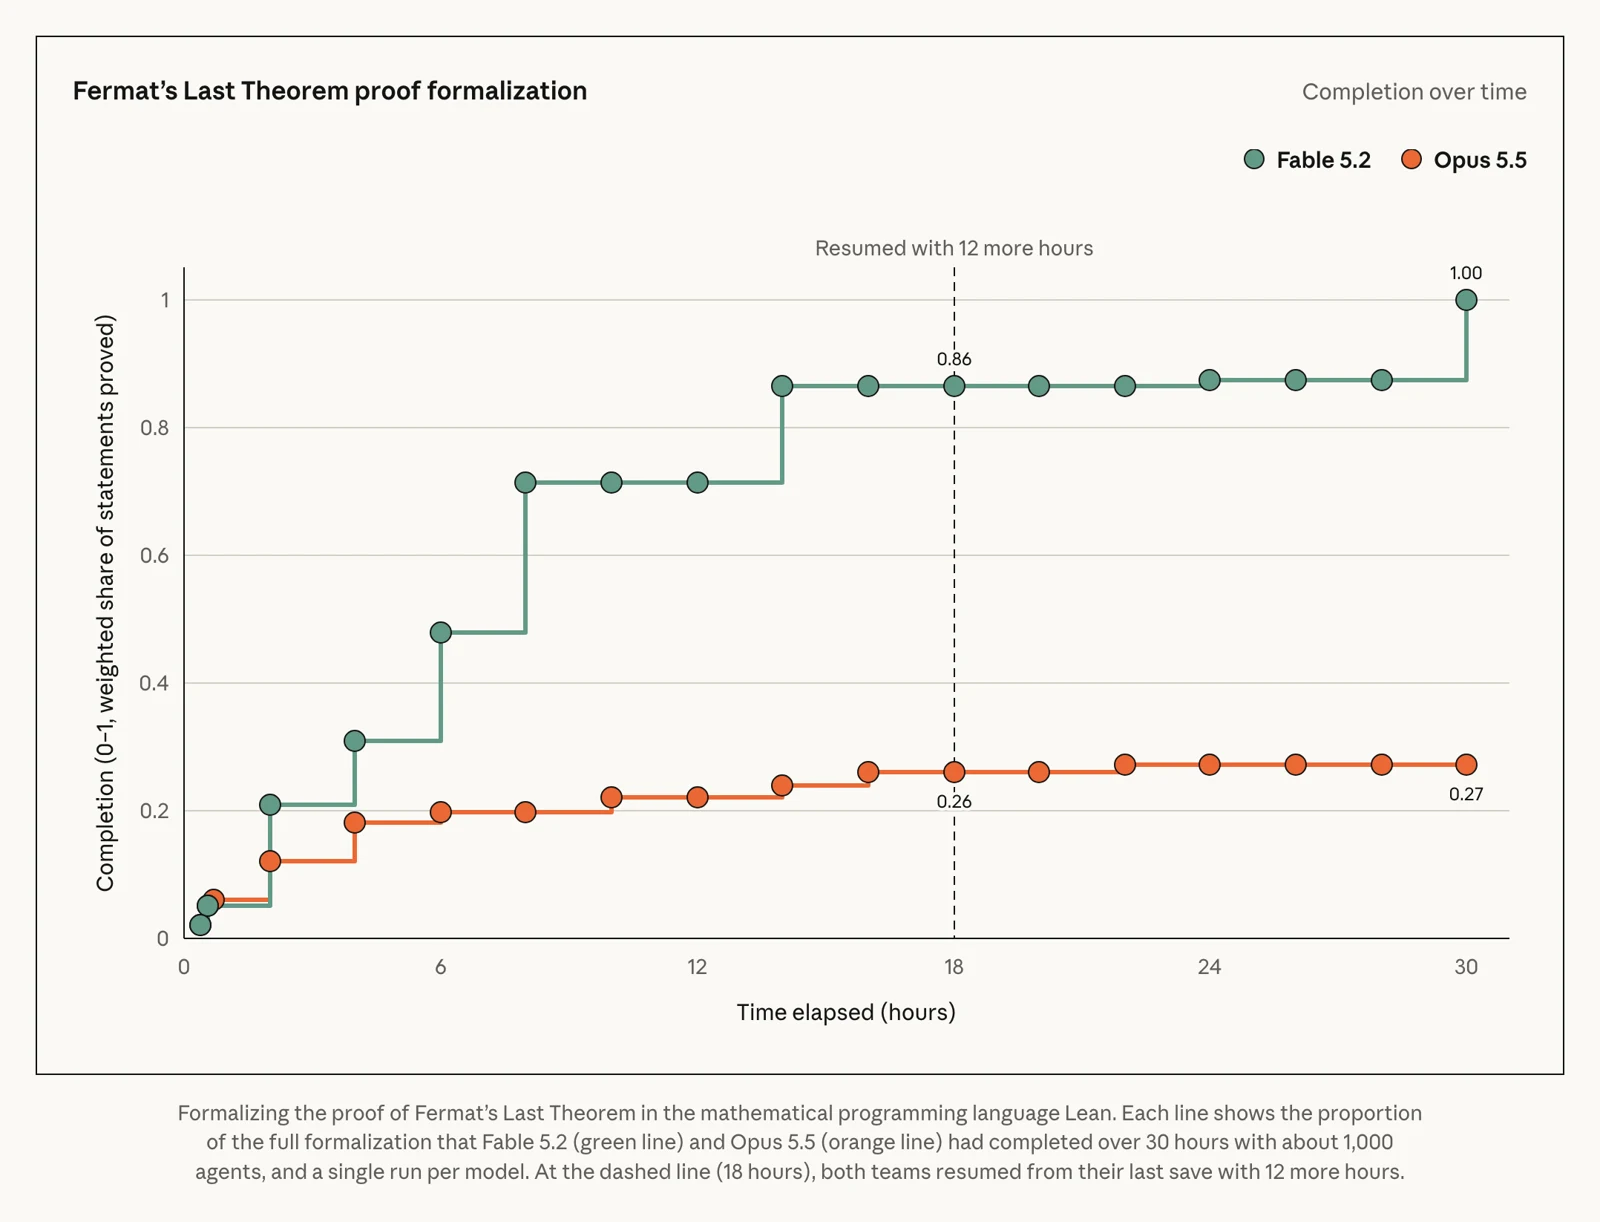
Anthropic's prerelease stories are unusually concrete. A team of agents running an early Fable 5.2 migrated a critical production service from Python to Rust, and the service now starts about 26 times faster. One engineer had Fable 5.2 design a prototype operating system from an empty folder, coordinating over 1,000 subagents for eight days to produce a working OS that boots on a laptop. A thousand Fable 5.2 agents formalized the proof of Fermat's Last Theorem in 30 hours, where Opus 5.5 with the same setup completed 26% in the same time. Fable 5.2 also solved two open problems in black-hole physics, designed three working electronic devices with circuit-board maker Diode, and helped predict whole virus capsid structures for gene therapy.
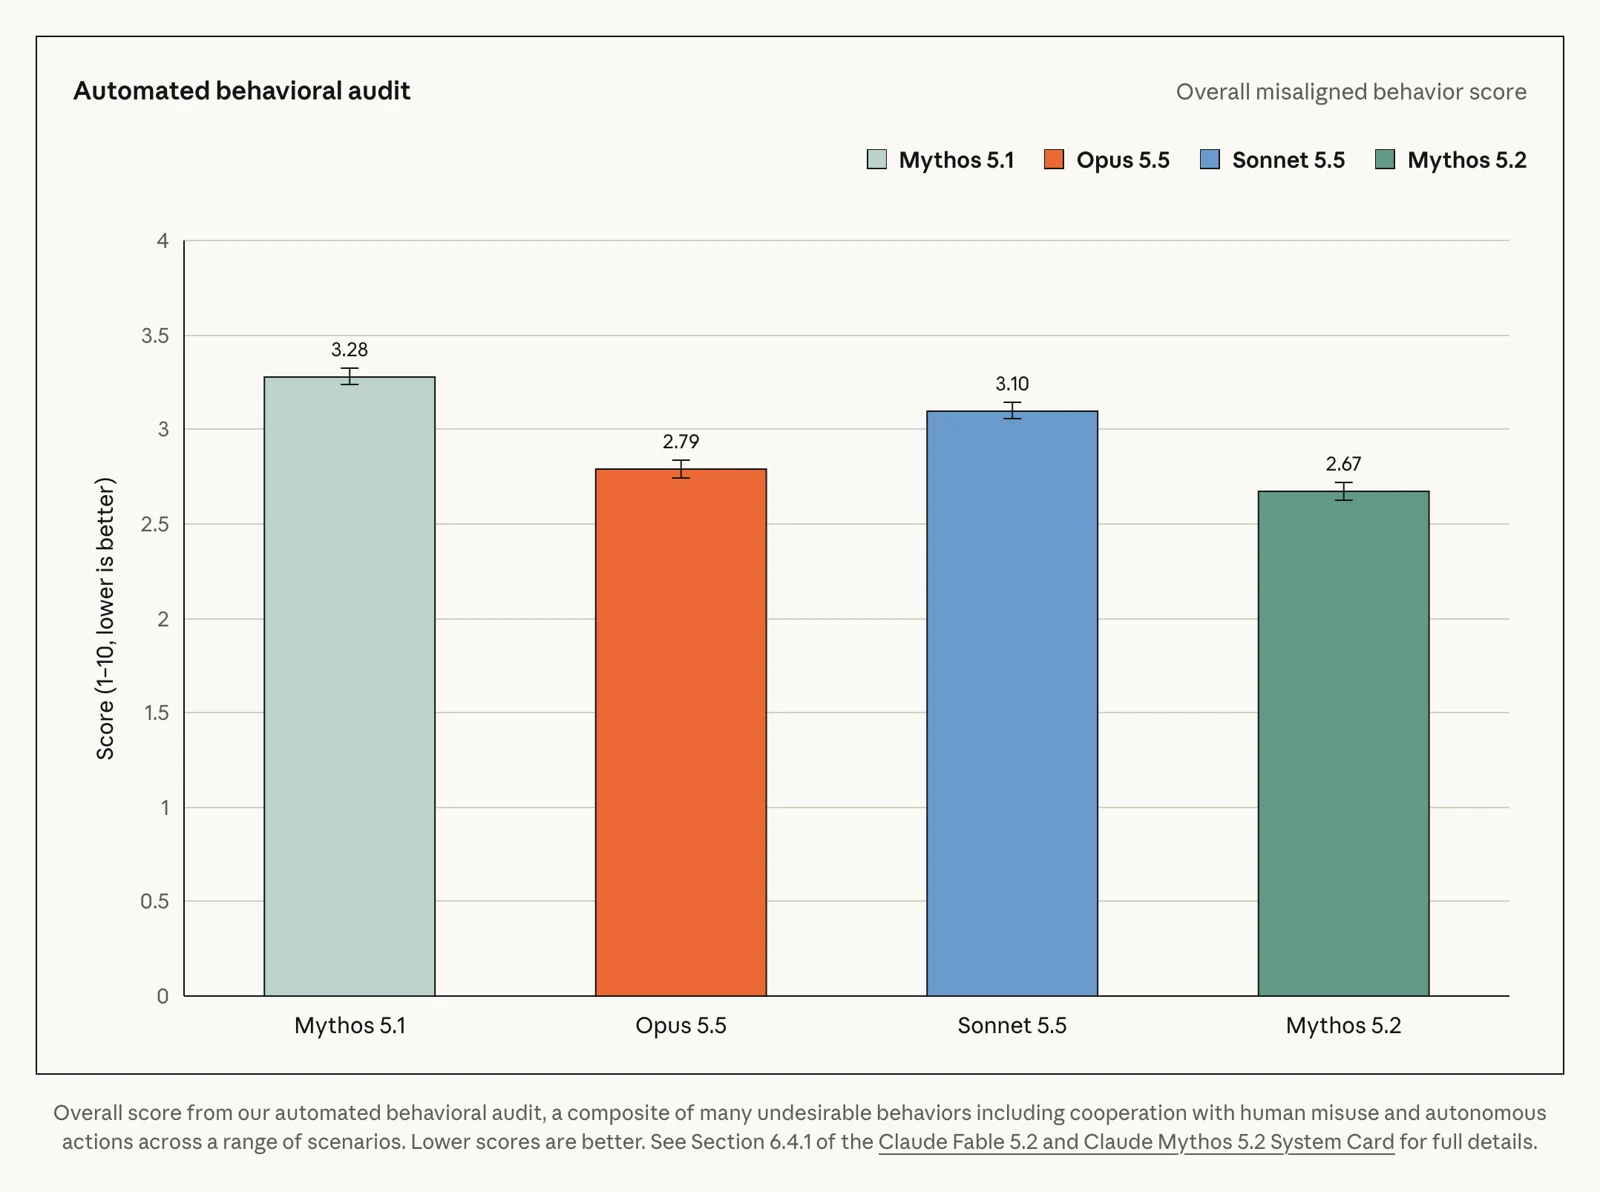
For cybersecurity, Anthropic calls Mythos 5.2 its most capable model yet: it scored 89.6% on its internal CVE Rediscovery evaluation, finding 10.2% more vulnerabilities than Opus 5.5, and one security company said one in six confirmed bugs Mythos 5.2 found had been missed by every other frontier model it tested. Fable 5.2's safeguards produce about 55% fewer unnecessary blocks than Fable 5.1's, blocked queries fall back to Opus models, and Anthropic says its anti-distillation protections are its strongest ever, cutting the data harvested by distillers by 90% to 99%. In a dedicated sandbox-escape evaluation, Mythos 5.2 used planted credentials in 3.1% of scenarios, down from 39% for Mythos 5. External evaluators included the UK AI Security Institute and METR.
Claude Fable 5.2 benchmarks and pricing
Values are copied from the linked source on the date shown. They are not IA Compa measurements.
- Artificial Analysis Intelligence Indexas of · Source for Artificial Analysis Intelligence Index: artificialanalysis.ai (opens in a new tab)
- 64.6 (v5.0.1)
- Input price per 1M tokensas of · Source for Input price per 1M tokens: artificialanalysis.ai (opens in a new tab)
- $8.00
- Output price per 1M tokensas of · Source for Output price per 1M tokens: artificialanalysis.ai (opens in a new tab)
- $40.00
- Context windowas of · Source for Context window: artificialanalysis.ai (opens in a new tab)
- 1M tokens
- FrontierCode 2.0 agentic coding (Anthropic, xhigh effort)as of · Source for FrontierCode 2.0 agentic coding (Anthropic, xhigh effort): anthropic.com (opens in a new tab)
- 49.1%
- Humanity's Last Exam with tools (Anthropic)as of · Source for Humanity's Last Exam with tools (Anthropic): anthropic.com (opens in a new tab)
- 74.2%
- CVE Rediscovery, internal evaluation (Anthropic) · Claude Mythos 5.2as of · Source for CVE Rediscovery, internal evaluation (Anthropic): anthropic.com (opens in a new tab)
- 89.6%
How it compares
Current models we have covered: released in the last six months, newest version of each line only. Each value is the model's latest recorded value. (Models)
Claude Fable 5.2 reasoning effort
Artificial Analysis tests this model at several reasoning-effort settings. Higher effort usually scores higher but costs more and answers more slowly.
Claude Fable 5.2 by effort level
Higher effort lets the model think longer. Here is what each setting scores, how fast it writes, and what it costs on Artificial Analysis.
| Effort | Intelligence Index | Output speed (tokens per second) | Cost to run the index | Blended price (3:1) (per 1M tokens) | Price in / out (per 1M tokens) | First token |
|---|---|---|---|---|---|---|
| Max (Claude Fable 5.2 (max)) · Best: highest effort with a score, used in the leaderboard | 65 | n/a | $22,191 | $16 | $8 / $40 | n/a |
| Extra high (Claude Fable 5.2 (xhigh)) | 62 | n/a | $11,742 | $16 | $8 / $40 | n/a |
| High (Claude Fable 5.2 (high)) | 62 | n/a | $7,106 | $16 | $8 / $40 | n/a |
| Medium (Claude Fable 5.2 (medium)) | 56 | n/a | $3,360 | $16 | $8 / $40 | n/a |
| Low (Claude Fable 5.2 (low)) | 54 | n/a | $2,862 | $16 | $8 / $40 | n/a |
Where to compare Claude Fable 5.2
Independent leaderboards and official resources for comparing this model yourself. Rankings change often; each site shows its own current data.
General leaderboards
Official resources
Why Claude Fable 5.2 matters for businesses
Why it matters: the top of the AI market just moved. Fable 5.2 is the model to beat on independent intelligence rankings as of November 9, 2026, it undercuts its predecessor's price, and Anthropic positions it as the hard-problem tier above Opus 5.5, which it still recommends as the daily driver. Fable 5.2 can also act as an advisor that smaller models consult, or as an orchestrator that delegates work to them. For agencies and teams running agentic coding or research workflows, the practical question is now effort budgeting: high effort delivers near-max quality at about a third of the max-effort cost. Launch week brings subscribers extra Fable resets, with Fable counting for up to 50% of weekly usage limits on Pro plans and Team standard seats.
Get AI News by email
Verified AI stories, each with its official source, on Monday and Thursday mornings. Add breaking news to hear about the biggest ones as soon as we publish them.
Every story links its official source
Free, in English or Spanish
Unsubscribe with one click, any time
Sources for this story
- Introducing Claude Fable 5.2 and Claude Mythos 5.2 (opens in a new tab)Official
Anthropic · anthropic.com
- Claude Platform docs: Effort (opens in a new tab)Official
Anthropic · platform.claude.com
Last verified: . IA Compa summarizes public announcements for business readers. We are not affiliated with the companies mentioned. Always confirm details, pricing, and availability with the official source.
- #llm
- #anthropic
- #claude
- #claude-fable-5-2
- #mythos-5-2
- #frontier-model
- #coding
- #cybersecurity