
Gemini 4 Neon at a glance
Google launched Gemini 4 Neon on November 18, 2026, a Gemini 4 model for complex coding, knowledge work and science, at $3 input and $15 output per million tokens. As of November 18, 2026, Artificial Analysis ranks it #3 overall on its Intelligence Index at 61 (xhigh) and #1 on its Coding Agent Index at 58.6.
Current standing
As of
- Rank
- #3of 50 models
Gemini 4 Neon (XHigh) · 61.4 on the Artificial Analysis Intelligence Index v5.0.1 (opens in a new tab)
- Recorded at publication
- 61 (v5.0.1)
as of
- Current leader
- Claude Fable 5.2 (Anthropic) · 64.6
Computed from our daily snapshot; it changes as new models are measured. Google launches Gemini 4 Neon, its Gemini 4 model for coding and knowledge work, at $3/$15 per million tokens
Ask your AI about this story
Ask what changed in Gemini 4 Neon and what to check before using it in your business. Compare it on price, speed, intelligence and the price-to-speed ratio against the models I would otherwise use, and say which tasks it suits or does not suit.
What changed with Gemini 4 Neon
Google DeepMind launched Gemini 4 Neon on November 18, 2026, the fourth model in the Gemini 4 family, built for complex software engineering, knowledge work and science workflows. It is rolling out today in the Gemini API's paid tier in Google AI Studio and Android Studio, in Gemini for business, in Google Antigravity for paid AI Pro and Ultra subscribers, and in the Gemini app for Pro and Ultra subscribers. Google describes Neon as “bringing frontier-level intelligence with fast end-to-end task completion,” positioned between the faster Gemini 4 Hydrogen and the stronger Gemini 4 Carbon.
Gemini 4 Neon (model ID gemini-4-neon) costs $3 per million input tokens, $0.15 per million cached input tokens and $15 per million output tokens, with a 1M-token context window. It offers four thinking levels — low, medium, high and xhigh — through the thinking_level parameter, with high as the default. Artificial Analysis measured the xhigh setting at about $6.44 per task on its Intelligence Index evaluations as of November 18, 2026, about 17% less than Gemini 4 Carbon's $7.76, and about 21 minutes per task, roughly 40% faster than Carbon; from December 1, when Carbon's promotional $2/$10 pricing ends and its standard $4/$20 applies, Neon is 25% cheaper per token.
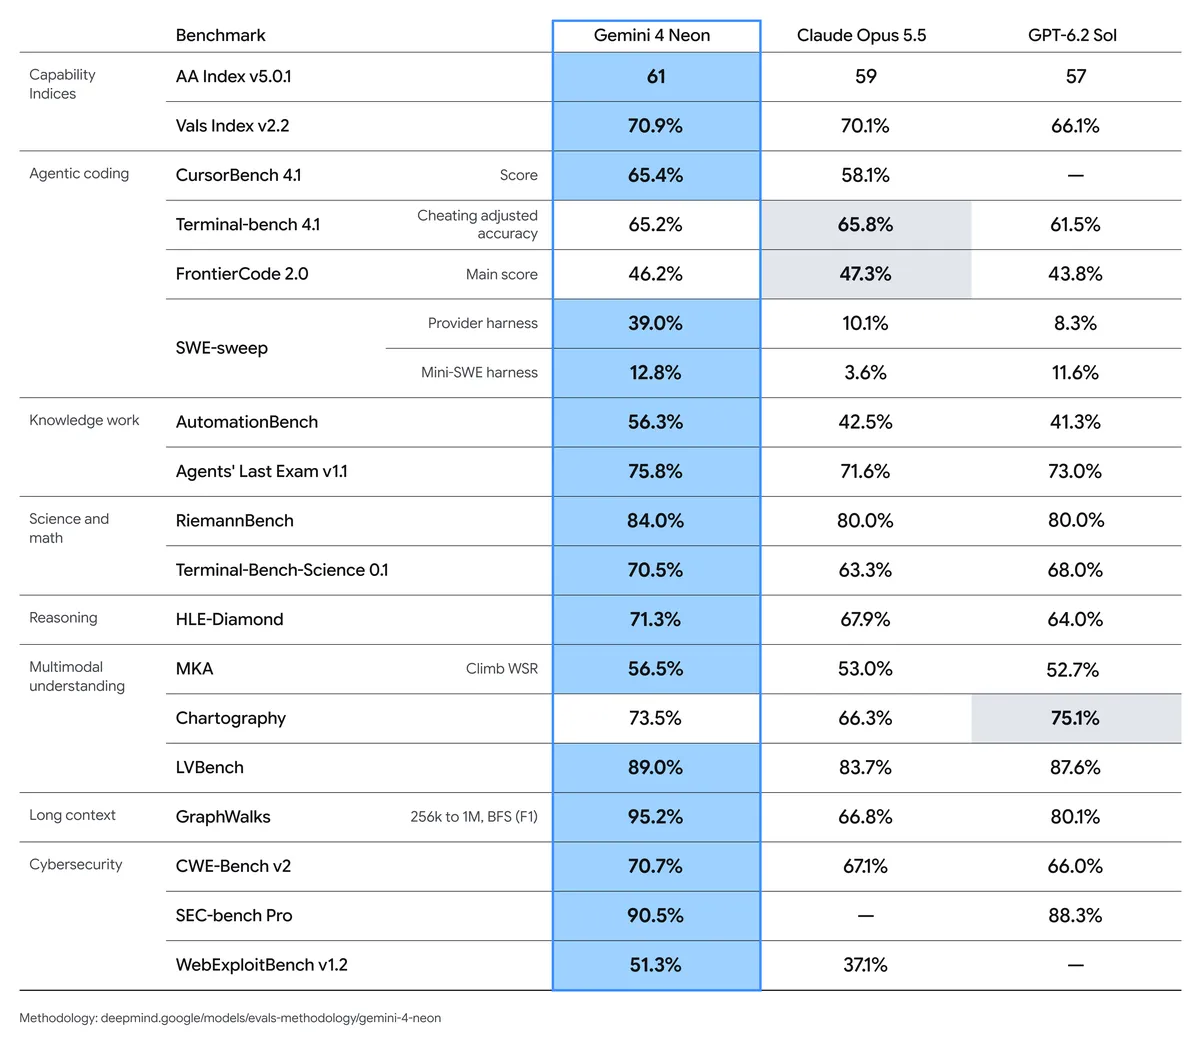
Google's launch benchmark table for Gemini 4 Neon against Claude Opus 5.5 and GPT-6.2 Sol.
As of November 18, 2026, Artificial Analysis scored Gemini 4 Neon at 61 on its Intelligence Index at xhigh — #3 overall, behind Claude Fable 5.2 and GPT-6.2 Astra and one point ahead of Gemini 4 Carbon — at about 110 output tokens per second. Artificial Analysis also ranks it #1 overall on its Coding Agent Index at 58.6, as of November 18, 2026. Google reports #2 on the Vals Index at 70.9% and a #2 debut on Arena's Agent Arena Index with a score of 1336, both as of November 18, 2026, plus 65.2% on Terminal-Bench 4.1 and 75.8% on Agents' Last Exam v1.1. A Gemini 4 Neon for cyber variant rolls out to trusted defenders through the Fairwind Program in the coming days.
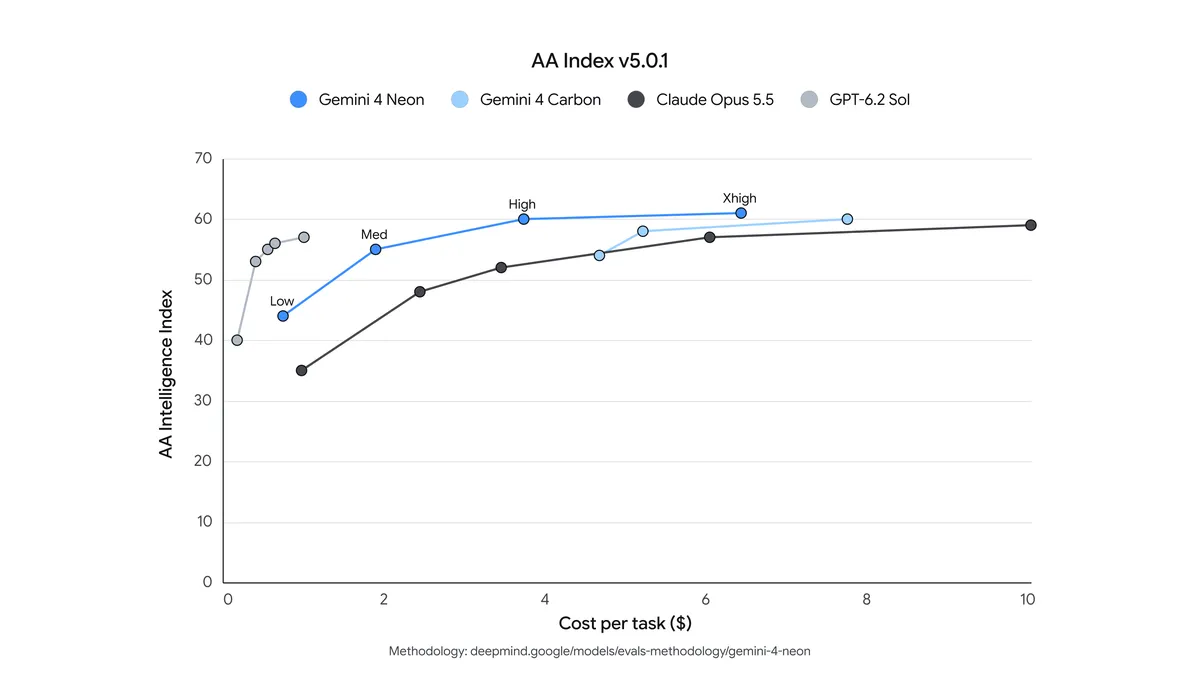
Artificial Analysis Index v5.0.1 score versus cost per task for Gemini 4 Neon and rival models, from Google's announcement.
Gemini 4 Neon benchmarks and pricing
Values are copied from the linked source on the date shown. They are not IA Compa measurements.
- Artificial Analysis Intelligence Index (xhigh)as of · Source for Artificial Analysis Intelligence Index (xhigh): artificialanalysis.ai (opens in a new tab)
- 61 (v5.0.1)
- Output speed (xhigh)as of · Source for Output speed (xhigh): artificialanalysis.ai (opens in a new tab)
- 110 tokens/s
- Input price per 1M tokensas of · Source for Input price per 1M tokens: blog.google (opens in a new tab)
- $3.00
- Output price per 1M tokensas of · Source for Output price per 1M tokens: blog.google (opens in a new tab)
- $15.00
- Context windowas of · Source for Context window: artificialanalysis.ai (opens in a new tab)
- 1M tokens
- Artificial Analysis Coding Agent Indexas of · Source for Artificial Analysis Coding Agent Index: artificialanalysis.ai (opens in a new tab)
- 58.6 (#1 overall)
How it compares
Current models we have covered: released in the last six months, newest version of each line only. Each value is the model's latest recorded value. (Models)
Gemini 4 Neon reasoning effort
Artificial Analysis tests this model at several reasoning-effort settings. Higher effort usually scores higher but costs more and answers more slowly.
Gemini 4 Neon by effort level
Higher effort lets the model think longer. Here is what each setting scores, how fast it writes, and what it costs on Artificial Analysis.
| Effort | Intelligence Index | Output speed (tokens per second) | Cost to run the index | Blended price (3:1) (per 1M tokens) | Price in / out (per 1M tokens) | First token |
|---|---|---|---|---|---|---|
| Extra high (Gemini 4 Neon (xhigh)) · Best: highest effort with a score, used in the leaderboard | 61 | 110 | $7,788 | $6 | $3 / $15 | 57 s |
| High (Gemini 4 Neon (high)) | 60 | 102 | $3,695 | $6 | $3 / $15 | 41 s |
| Medium (Gemini 4 Neon (medium)) | 55 | 101 | $1,866 | $6 | $3 / $15 | 20 s |
| Low (Gemini 4 Neon (low)) | 44 | 97 | $830 | $6 | $3 / $15 | 14 s |
Where to compare Gemini 4 Neon
Independent leaderboards and official resources for comparing this model yourself. Rankings change often; each site shows its own current data.
Leaderboards
General leaderboards
Why Gemini 4 Neon matters for businesses
Why it matters: businesses get a frontier coding and knowledge-work model that finishes agent tasks about 40% faster than Gemini 4 Carbon at a lower cost per task, so teams can run longer coding, research and document workflows for less. The four thinking levels let a business pay for deep reasoning only on hard jobs and use the cheaper, faster settings for routine work, and the Gemini API, Antigravity and Gemini app rollouts mean most teams can start testing it today without new contracts.
Put it to work: AI services
Get AI News by email
Verified AI stories, each with its official source, on Monday and Thursday mornings. Add breaking news to hear about the biggest ones as soon as we publish them.
Every story links its official source
Free, in English or Spanish
Unsubscribe with one click, any time
Sources for this story
- Introducing Gemini 4 Neon (opens in a new tab)Official
Google · blog.google
- Gemini 4 Neon model page (Gemini API docs) (opens in a new tab)Official
Google · ai.google.dev
- Gemini 4 Neon model page (opens in a new tab)Benchmark
Artificial Analysis · artificialanalysis.ai
- Gemini 4 Neon: Intelligence gain at the same price (opens in a new tab)Benchmark
Artificial Analysis · artificialanalysis.ai
- Artificial Analysis LLM Leaderboard (opens in a new tab)Benchmark
Artificial Analysis · artificialanalysis.ai
Last verified: . IA Compa summarizes public announcements for business readers. We are not affiliated with the companies mentioned. Always confirm details, pricing, and availability with the official source.
- #llm
- #gemini
- #gemini-4
- #coding-agents
- #frontier-model
- #pricing


